
evren-sdk
EVREN Yapay Zeka Platformu — Resmi Python SDK


Türkçe · English · Examples · Changelog
🇹🇷 Türkçe
EVREN Yapay Zeka Platformu'nun resmi Python SDK'sı: platformda eğitilmiş bilgisayarlı görü modelleriyle çıkarım ve EVREN LLM geçidi (sohbet, akış, embedding, rerank).
Nesne tespiti · Sınıflandırma · Segmentasyon · OBB · Keypoint · Edge Inference · LLM Geçidi
Mimari
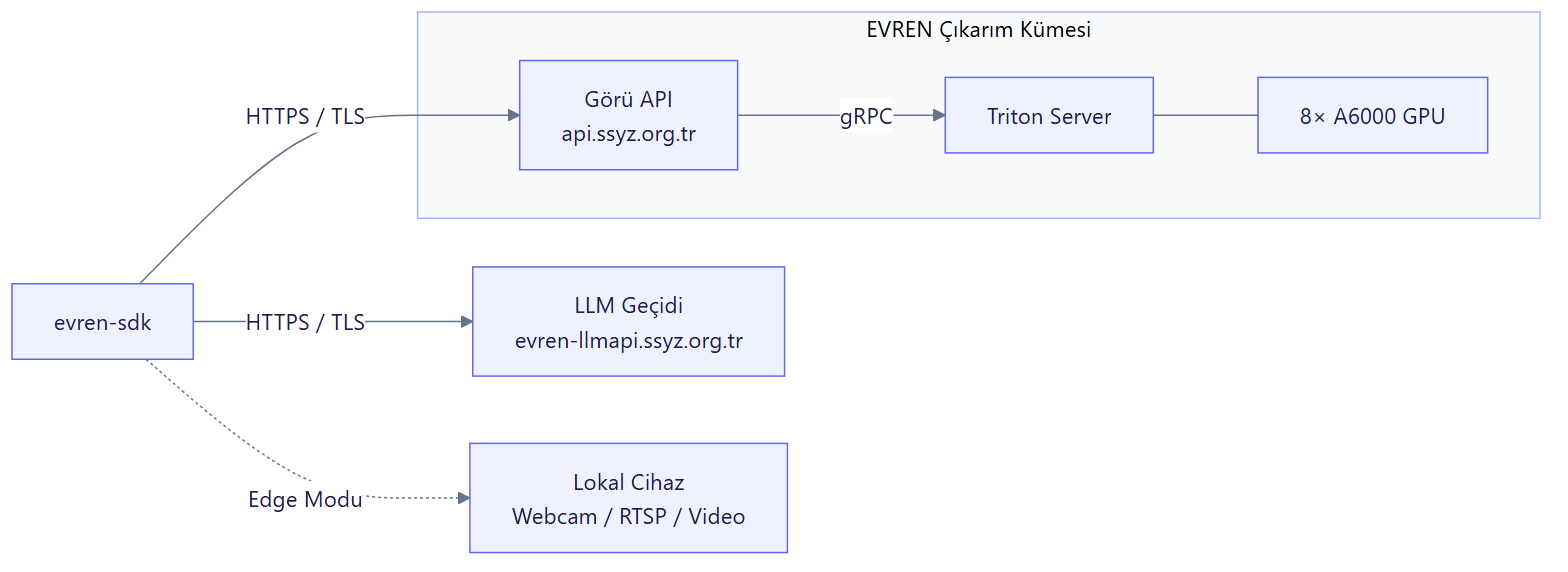
Tek bir predict() çağrısının arkasında 8× NVIDIA A6000 GPU çalışır.
Kullanıcı altyapı yönetmez — pip install ve 3 satır kod yeter.
Kurulum
pip install evren-sdk            # temel SDK
pip install evren-sdk[edge]      # + OpenCV (kamera/video)
Hızlı Başlangıç
from evren_sdk import EvrenClient

client = EvrenClient(api_key="evren_xxxxx")
result = client.predict("kullanici/model-adi", "foto.jpg", confidence=0.3)

for det in result.predictions:
    print(f"{det.class_name}: {det.confidence:.0%}  bbox={det.bbox}")
Daha fazla örnek için examples/ dizinine bakın.
Kimlik Doğrulama
Platformda Ayarlar → API Anahtarları sayfasından anahtar oluşturun.
Anahtar evren_ ön eki ile başlar.
client = EvrenClient(api_key="evren_xxxxx")    # API anahtarı (önerilen)
client = EvrenClient(api_key="eyJhbGci...")    # JWT token
Çıkarım Akışı
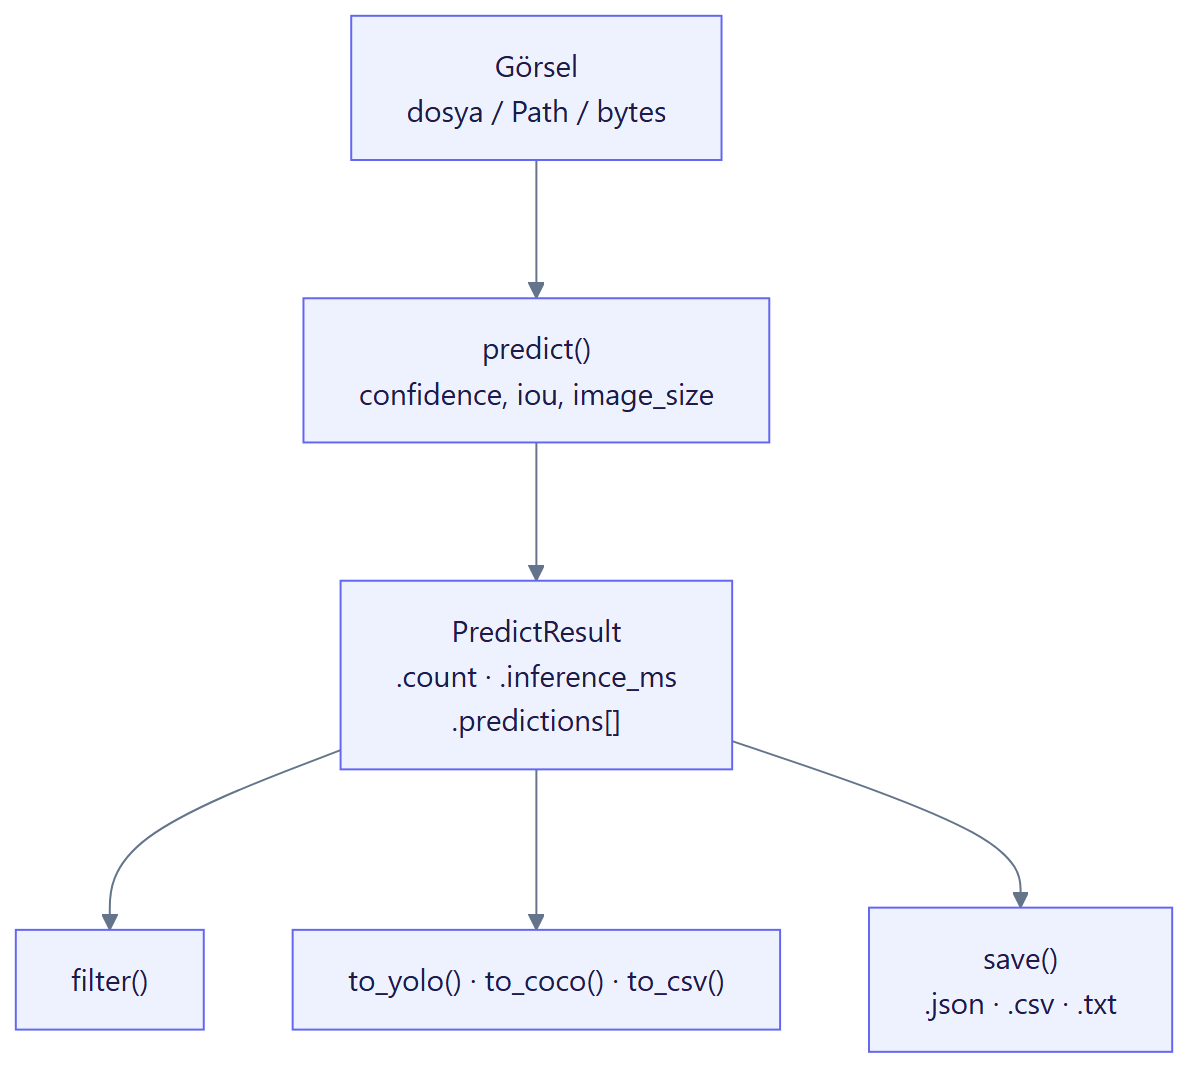
Tekil Çıkarım
result = client.predict(
    model="kullanici/model-adi",        # slug, slug:tag veya UUID
    image="resim.jpg",                  # dosya yolu, Path veya bytes
    confidence=0.25,
    iou=0.45,
    image_size=640,
    classes=["araba", "insan"],         # isteğe bağlı
)
model Formatı |
Açıklama |
|---|---|
"owner/slug" |
Son versiyonu otomatik çözer |
"owner/slug:v2.0" |
Belirli versiyon etiketi |
"019cec..." (UUID) |
Doğrudan versiyon ID |
Toplu Çıkarım (Batch)
batch = client.predict_batch(
    model="kullanici/model-adi",
    images=["img1.jpg", "img2.jpg", "img3.jpg"],
    confidence=0.3,
)

for r in batch:
    print(f"{r.count} tespit, {r.inference_ms:.0f} ms")
Bkz. examples/02_batch_inference.py
Sonuç İşleme & Export
result = client.predict("kullanici/model", "sahne.jpg")

# filtrele
filtre = result.filter(min_confidence=0.5, classes=["araba"])

# export
result.to_yolo()          # YOLO txt format
result.to_coco()          # COCO dict list
result.to_csv()           # CSV string

# dosyaya kaydet (format uzantıdan anlaşılır)
result.save("sonuc.json")
result.save("sonuc.csv")
result.save("labels.txt")
Detay: examples/03_result_export.py
Model Bilgileri & Warmup
# sınıfları listele
info = client.model_classes("kullanici/model-adi")
for cls in info.classes:
    print(f"  {cls.name}: {cls.color}")

# mevcut modelleri listele
for m in client.list_models():
    print(f"{m.full_slug} — {m.architecture}")

# GPU'ya ön-yükleme (cold-start elimine)
client.warmup(["kullanici/model-adi"])
Performans Testi
bench = client.benchmark("kullanici/model", "test.jpg", rounds=20)

print(f"Avg: {bench.avg_ms:.1f}ms  |  p95: {bench.p95_ms:.1f}ms")
print(f"Min: {bench.min_ms:.1f}ms  |  Max: {bench.max_ms:.1f}ms")
print(f"Throughput: {bench.throughput_fps:.1f} FPS")
Model İndirme
path = client.download_model("kullanici/model", output="weights/", fmt="onnx")
print(f"Kaydedildi: {path}")   # weights/best.onnx
Veri Setine Görsel Yükleme
SDK üzerinden doğrudan bir veri setine görsel yükleyebilirsiniz.
resp = client.upload_to_dataset(dataset_id="<UUID>", image="yeni_gorsel.jpg")
Asenkron Kullanım
import asyncio
from evren_sdk import AsyncEvrenClient

async def main():
    async with AsyncEvrenClient(api_key="evren_xxxxx") as client:
        result = await client.predict("kullanici/model", "foto.jpg")
        batch  = await client.predict_batch("kullanici/model", ["a.jpg", "b.jpg"])

asyncio.run(main())
Paralel pipeline için examples/07_async_pipeline.py
LLM Geçidi (Sohbet, Akış, Embedding, Rerank, Karar, OCR, Ses)
EvrenLLMClient, EVREN LLM geçidine (evren-llmapi.ssyz.org.tr) bağlanır.
Görü istemcisinden ayrıdır ve evren_llm_... ile başlayan LLM anahtarı kullanır.
Anahtar verilmezse EVREN_LLM_API_KEY ortam değişkeninden okunur.
from evren_sdk import EvrenLLMClient

with EvrenLLMClient() as llm:                       # EVREN_LLM_API_KEY
    print(llm.list_models())

    r = llm.chat("glm-5.3", [{"role": "user", "content": "Merhaba"}], max_tokens=512)
    print(r.content)          # yanıt metni (hiçbir zaman None değildir)
    print(r.reasoning)        # düşünen modellerde düşünme metni
    print(r.usage)            # token kullanımı
    print(r.request_id)       # destek talebinde paylaşın

    # akış — yalnızca metin
    for parca in llm.chat_stream("deepseek-v4.1-flash", [{"role": "user", "content": "Bir şiir yaz"}]):
        print(parca, end="", flush=True)

    # akış — ayrıntılı: düşünme metni, araç çağrıları, son parçada kullanım
    for d in llm.stream("glm-5.3", [{"role": "user", "content": "2+2?"}]):
        if d.reasoning: ...
        if d.content: print(d.content, end="")
        if d.usage: print("\n", d.usage)

    vektorler = llm.embed("qwen3-embedding-8b", ["merhaba", "dünya"])
    sirali = llm.rerank("qwen3-reranker-8b", "Türkiye'nin başkenti",
                        ["Paris Fransa'dadır", "Ankara başkenttir"], top_n=1)
Araç çağrısı (function calling) OpenAI biçimiyle çalışır; sonuç r.tool_calls alanındadır:
tools = [{"type": "function", "function": {"name": "hava", "parameters": {
    "type": "object", "properties": {"sehir": {"type": "string"}}, "required": ["sehir"]}}}]
r = llm.chat("glm-5.3", [{"role": "user", "content": "Ankara'da hava nasıl?"}], tools=tools)
for call in r.tool_calls:
    print(call["function"]["name"], call["function"]["arguments"])
Güvenilirlik. 429, 502, 503, 504 ve bağlantı hatalarında istemci Retry-After
başlığına uyarak otomatik tekrar dener (max_retries=2). Akışsız her çağrıya bir
Idempotency-Key eklenir; tekrar denenen istek geçitte tekilleştirilir, çift
çalıştırılmaz ve çift ücretlendirilmez. Akışlar yalnızca istek modele ulaşmadan
reddedildiyse (429/503) tekrar denenir. Akış yarıda kesilirse LLMServiceError
(code="stream_interrupted") fırlatılır; eksik yanıt tamamlanmış gibi dönmez.
Günlük kota dolduğunda geçit Retry-After değerini gün sonuna kadar verir; bu
durumda (30 sn'den uzun bekleme) tekrar denenmez, LLMRateLimitError hemen döner.
from evren_sdk import EvrenLLMError, LLMRateLimitError

try:
    llm.chat("glm-5.3", mesajlar)
except LLMRateLimitError as e:
    print(e.retry_after, e.evren.get("resets_at"))
except EvrenLLMError as e:
    print(e.status_code, e.code, e.request_id, e.evren)
Asenkron kullanım için AsyncEvrenLLMClient aynı yüzeyi sunar
(await llm.chat(...), async for parca in llm.chat_stream(...)).
Tipli Karar, OCR, Ses ve Kota
Karar modelleri (laya, clef) metin üretmez; bir metin (ve clef'te görsel) için
tanımladığınız choice, score ve noul (evet/hayır) sorularını tek geçişte
olasılıklarıyla yanıtlar. Hangi modelin hangi işi yaptığı llm.models() içindeki
task alanında yazar (decision, ocr, audio_transcription ...). Laya her
soruda instructions ister; iki modelde de çalışması için her soruya yazın.
from evren_sdk import EvrenLLMClient, encode_image

with EvrenLLMClient() as llm:
    r = llm.decide("clef", "Faturamdan iki kez ücret çekildi, iade etmezseniz iptal edeceğim.", {
        "birim": {"type": "choice", "instructions": "Hangi birim?",
                  "criteria": {"fatura": "ödeme, iade", "teknik": "hata, kesinti"}},
        "aciliyet": {"type": "score", "instructions": "Ne kadar acil?",
                     "criteria": ["acil değil", "yakında", "kritik"]},
        "iptal": {"type": "noul", "instructions": "İptal tehdidi var mı?"},
    })
    print(r.choice("birim"), r.score("aciliyet"), r.noul("iptal"), r.probabilities("birim"))

    # clef görsel de okur (en fazla 4). Görsel küçültülmeden okunur: 32×32 piksellik
    # her karo 1 token (1024 px ≈ 1.000, 4000 px ≈ 15.600) — büyük fotoğrafı küçültün:
    belge = encode_image("fatura.jpg", max_side=1024)   # pip install evren-sdk[images]
    r = llm.decide("clef", "Ekteki belgeyi incele.", {
        "okunakli": {"type": "noul", "instructions": "Toplam tutar okunaklı mı?"},
    }, images=[belge])

    # laya: aynı soruları 64 metne tek çağrıda (clef'te toplu uç yok)
    toplu = llm.decide_batch("laya", ["Şifremi unuttum", "Fiyat teklifi istiyorum"], {
        "birim": {"type": "choice", "instructions": "Hangi birim?",
                  "criteria": {"teknik": "giriş, hata", "satis": "fiyat, paket"}},
    })
    print([x.choice("birim") for x in toplu.results])

    print(llm.ocr("dots-ocr", "fis.png").text)                       # görselden metin
    print(llm.transcribe("qwen3-asr-1.7b", "toplanti.wav", language="tr").text)
    altyazi = llm.transcribe("qwen3-asr-1.7b", "video.mp3", response_format="srt").text

    ses = llm.speak("voxcpm2", "Raporunuz hazır. Doğruluk oranı yüzde 94,7.",
                    voice="deniz")   # hazır sesler: deniz, ece, emre, kaan - ayrı isteklerde de aynı ses
    ses.save("rapor.mp3")  # mp3 (varsayılan), wav, flac, opus, pcm

    q = llm.quota()        # 5 dk pencere, günlük tavan, kredi
    print(q.level, q.daily_remaining_tokens, q.remaining_cr)

    yanit = llm.respond("glm-5.3", "Türkiye'nin başkenti?")          # Responses API
    devam = llm.respond("glm-5.3", "Nüfusu?", previous_response_id=yanit.id)
    print(devam.output_text)
Ses ucunda geçit Idempotency-Key desteklemediği için transcribe() yalnızca
bağlantı hiç kurulamadıysa tekrar denenir. speak() için de aynısı geçerlidir;
4.096 karaktere kadar metni geçit cümle sınırlarından bölüp tek dosya döndürür.
voice dört hazır sesten birini seçer (deniz, ece, emre, kaan; varsayılan
default = deniz); aynı sesle yapılan ayrı çağrılar aynı konuşmacıyla okunur.
instructions (İngilizce tarif) verilirse ses tarife göre üretilir ve çağrılar
arasında birebir aynı ses garanti edilmez.
Edge Modu (GPU'suz Cihazlar)
GPU olmayan cihazlarda (Raspberry Pi, laptop, endüstriyel PC) gerçek zamanlı çıkarım. Çıkarım EVREN GPU'larında çalışır — lokal deneyim hissi verir.
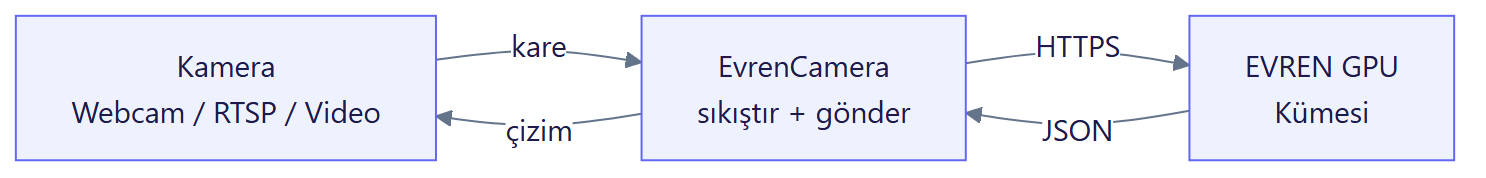
pip install evren-sdk[edge]
from evren_sdk import EvrenCamera

cam = EvrenCamera("evren_...", "kullanici/model", confidence=0.3)

cam.run(0)                                      # webcam, ESC ile kapat
cam.record("input.mp4", "output.mp4")           # video işle + kaydet

for frame, result in cam.stream(0):             # kendi loop'unuz
    print(f"{result.count} tespit")

for path, result in cam.scan("images/"):        # klasör tarama
    print(f"{path.name}: {result.count} nesne")
| Parametre | Varsayılan | Açıklama |
|---|---|---|
max_fps |
15.0 |
Bant genişliği koruma limiti |
jpeg_quality |
70 |
Sıkıştırma kalitesi (20-95) |
draw |
True |
Tahminleri frame üzerine çiz |
confidence |
0.25 |
Minimum güven eşiği |
Bkz. examples/05_edge_camera.py
Hata Yönetimi
from evren_sdk import (
    EvrenClient, InsufficientCreditsError,
    NotFoundError, RateLimitError, InferenceError,
)

client = EvrenClient(api_key="evren_xxxxx")

try:
    result = client.predict("kullanici/model", "test.jpg")
except InsufficientCreditsError as e:
    print(f"Kredi yetersiz — gerekli: {e.required}, bakiye: {e.available}")
except NotFoundError:
    print("Model bulunamadı")
except RateLimitError as e:
    time.sleep(e.retry_after)
except InferenceError:
    print("GPU sunucusu geçici olarak kullanılamıyor")
| Exception | HTTP | Açıklama |
|---|---|---|
AuthenticationError |
401, 403 | Geçersiz veya süresi dolmuş anahtar |
InsufficientCreditsError |
402 | Kredi bakiyesi yetersiz |
NotFoundError |
404 | Model veya versiyon bulunamadı |
ValidationError |
422 | Hatalı parametre |
RateLimitError |
429 | İstek limiti aşıldı |
InferenceError |
502, 503 | GPU sunucusu hatası |
Her çıkarım kredi tüketir. Bakiye yetersizse SDK
InsufficientCreditsErrorfırlatır —e.requiredvee.availablealanları bakiye bilgisini taşır.
API Referansı
Veri Modelleri
| Sınıf | Alanlar / Metotlar |
|---|---|
PredictResult |
predictions, inference_ms, count, image_width, image_height |
| ↳ metotlar | filter(), to_yolo(), to_coco(), to_csv(), save() |
Prediction |
class_name, confidence, bbox, color, mask, keypoints, obb |
| ↳ metotlar | to_dict() |
BatchResult |
results, total_ms, count — iterable, len() destekler |
BenchmarkResult |
model, rounds, avg_ms, min_ms, max_ms, p95_ms, throughput_fps |
ModelClasses |
classes, architecture, model_name, total, imgsz — in operatörü |
| ↳ metotlar | names() |
ModelInfo |
id, name, slug, architecture, owner_username, full_slug |
ModelVersion |
id, version_tag, framework, metrics, weights_url |
ClassInfo |
name, color |
EvrenCamera |
stream(), run(), scan(), record(), stats |
Client Metotları
| Metot | Açıklama |
|---|---|
predict(model, image, **kw) |
Tekil çıkarım |
predict_batch(model, images, **kw) |
GPU batch çıkarım |
model_classes(model) |
Model sınıfları, mimari, imgsz |
warmup(models) |
GPU ön-yükleme |
list_models(limit) |
Mevcut modelleri listele |
list_versions(model_id) |
Model versiyonlarını listele |
resolve(slug) |
Slug → version UUID çözümle |
benchmark(model, image, **kw) |
Performans testi |
download_model(model, output, fmt) |
Ağırlık dosyası indir |
upload_to_dataset(dataset_id, image) |
Veri setine görsel yükle |
AsyncEvrenClient aynı API'yi async/await ile sunar.
LLM İstemcisi Metotları
| Metot | Uç | Dönüş |
|---|---|---|
chat(model, messages, **kw) |
/v1/chat/completions |
ChatCompletionResult |
stream() / chat_stream() |
/v1/chat/completions (SSE) |
ChatDelta / str |
embed(model, texts) |
/v1/embeddings |
list[list[float]] |
rerank(model, query, documents, top_n) |
/v1/rerank |
list[RerankResult] |
decide(model, state, questions, images=) |
/v1/systemone |
DecisionResult |
decide_batch(model, states, questions) |
/v1/systemone/batch |
DecisionBatchResult |
ocr(model, image) |
/v1/ocr |
OcrResult |
transcribe(model, audio, response_format=) |
/v1/audio/transcriptions |
Transcription |
speak(model, text, voice=, response_format=, instructions=) |
/v1/audio/speech |
SpeechResult |
respond(model, input, **kw) / get_response(id) |
/v1/responses |
ResponseResult |
models() / list_models() |
/v1/models |
list[LLMModel] / list[str] |
quota() |
/v1/quota |
QuotaStatus |
request_status(request_id) |
/v1/requests/{id} |
RequestStatus |
encode_image(kaynak, max_side=None) yol, bayt ya da data: URL'yi geçidin kabul
ettiği gömülü biçime çevirir.
🇬🇧 English
Official Python SDK of the EVREN AI Platform: inference on computer vision models trained on EVREN and access to the EVREN LLM gateway (chat, streaming, embeddings, rerank).
Object Detection · Classification · Segmentation · OBB · Keypoint · Edge Inference · LLM Gateway
Architecture
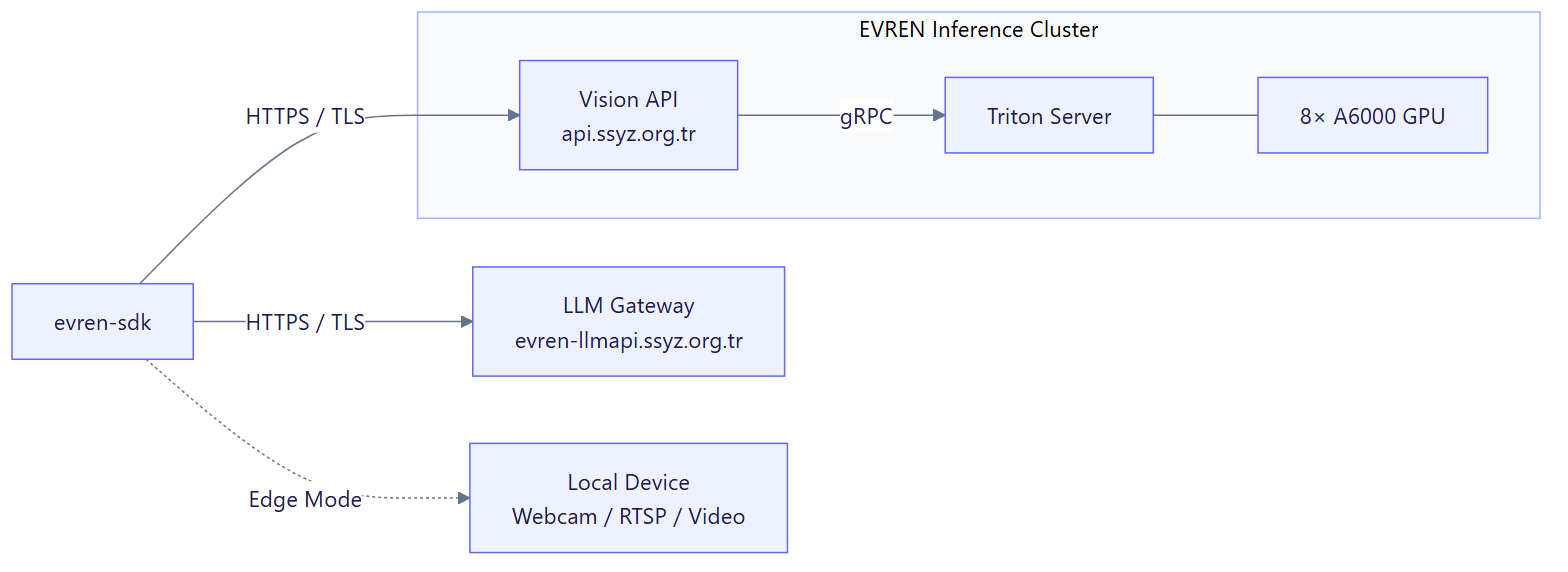
A single predict() call leverages 8× NVIDIA A6000 GPUs.
No infrastructure management — pip install and 3 lines of code.
Installation
pip install evren-sdk            # core SDK
pip install evren-sdk[edge]      # + OpenCV (camera/video support)
Quick Start
from evren_sdk import EvrenClient

client = EvrenClient(api_key="evren_xxxxx")
result = client.predict("owner/model-name", "photo.jpg", confidence=0.3)

for det in result.predictions:
    print(f"{det.class_name}: {det.confidence:.0%}  bbox={det.bbox}")
See examples/ for runnable scripts covering every feature.
Authentication
Create an API key from Settings → API Keys on the platform.
Keys start with the evren_ prefix.
client = EvrenClient(api_key="evren_xxxxx")    # API key (recommended)
client = EvrenClient(api_key="eyJhbGci...")    # JWT token
Inference Pipeline
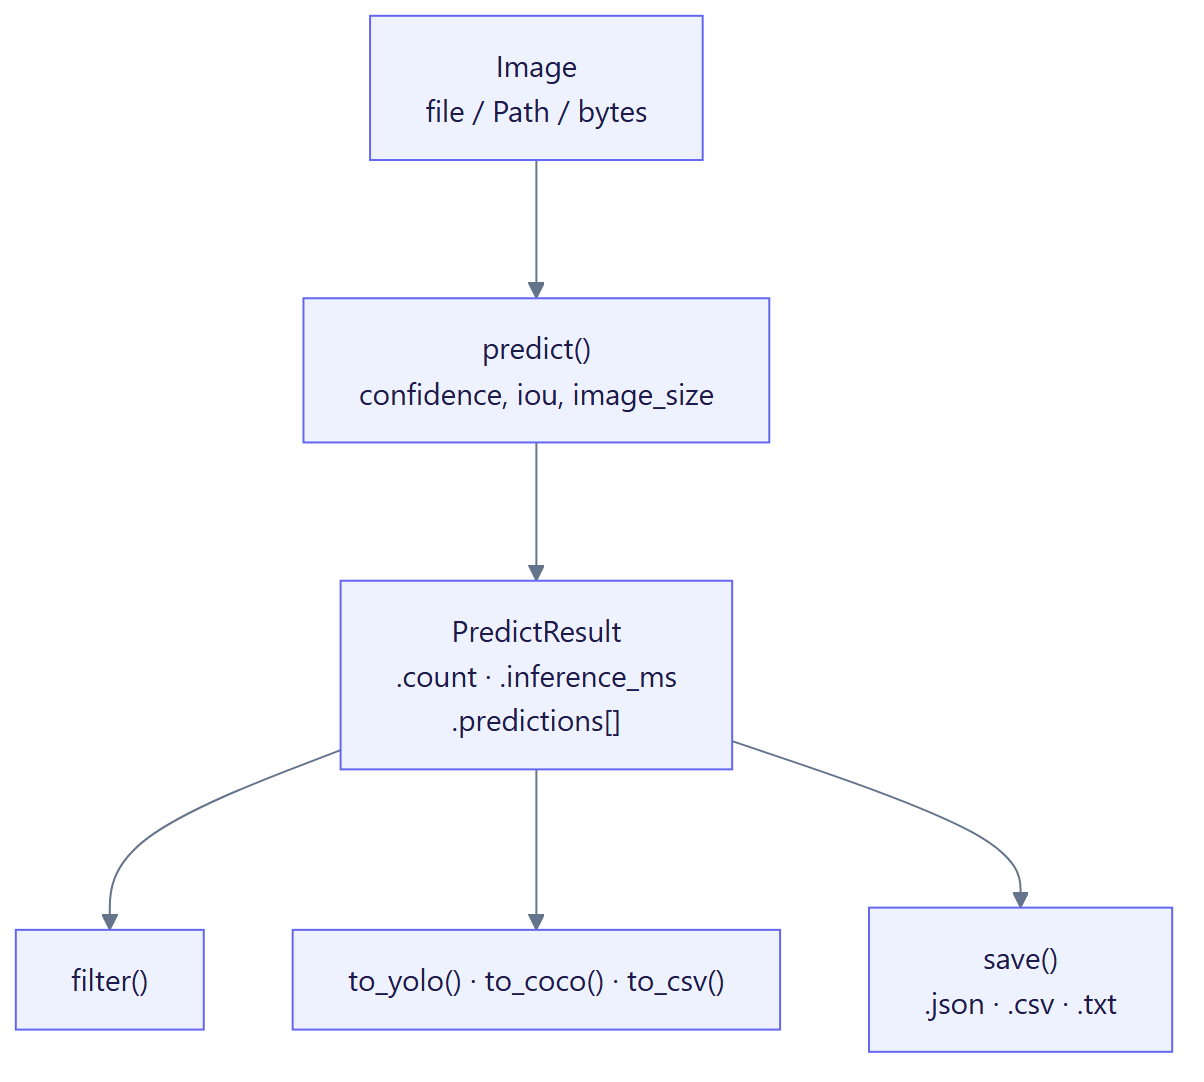
Single Prediction
result = client.predict(
    model="owner/model-name",           # slug, slug:tag, or UUID
    image="image.jpg",                  # file path, Path, or bytes
    confidence=0.25,
    iou=0.45,
    image_size=640,
    classes=["car", "person"],          # optional
)
model Format |
Description |
|---|---|
"owner/slug" |
Resolves to latest version |
"owner/slug:v2.0" |
Specific version tag |
"019cec..." (UUID) |
Direct version ID |
Batch Prediction
batch = client.predict_batch(
    model="owner/model-name",
    images=["img1.jpg", "img2.jpg", "img3.jpg"],
    confidence=0.3,
)

for r in batch:
    print(f"{r.count} detections, {r.inference_ms:.0f} ms")
See examples/02_batch_inference.py
Result Processing & Export
result = client.predict("owner/model", "scene.jpg")

filtered = result.filter(min_confidence=0.5, classes=["car"])

result.to_yolo()          # YOLO txt
result.to_coco()          # COCO dict list
result.to_csv()           # CSV string

result.save("result.json")
result.save("result.csv")
result.save("labels.txt")
Full example: examples/03_result_export.py
Model Info & Warmup
info = client.model_classes("owner/model-name")
for cls in info.classes:
    print(f"  {cls.name}: {cls.color}")

for m in client.list_models():
    print(f"{m.full_slug} — {m.architecture}")

client.warmup(["owner/model-name"])   # eliminate cold-start
Benchmarking
bench = client.benchmark("owner/model", "test.jpg", rounds=20)

print(f"Avg: {bench.avg_ms:.1f}ms  |  p95: {bench.p95_ms:.1f}ms")
print(f"Throughput: {bench.throughput_fps:.1f} FPS")
Model Download
path = client.download_model("owner/model", output="weights/", fmt="onnx")
print(f"Saved to: {path}")   # weights/best.onnx
Upload to Dataset
Upload images to a dataset directly from the SDK.
resp = client.upload_to_dataset(dataset_id="<UUID>", image="new_image.jpg")
Async Usage
import asyncio
from evren_sdk import AsyncEvrenClient

async def main():
    async with AsyncEvrenClient(api_key="evren_xxxxx") as client:
        result = await client.predict("owner/model", "photo.jpg")
        batch  = await client.predict_batch("owner/model", ["a.jpg", "b.jpg"])

asyncio.run(main())
Parallel pipeline: examples/07_async_pipeline.py
LLM Gateway (Chat, Streaming, Embeddings, Rerank, Decisions, OCR, Speech)
EvrenLLMClient talks to the EVREN LLM gateway (evren-llmapi.ssyz.org.tr). It is
separate from the vision client and uses an LLM key starting with evren_llm_.
If no key is passed, EVREN_LLM_API_KEY is used.
from evren_sdk import EvrenLLMClient

with EvrenLLMClient() as llm:
    r = llm.chat("glm-5.3", [{"role": "user", "content": "Hello"}], max_tokens=512)
    print(r.content, r.reasoning, r.usage, r.request_id)

    for chunk in llm.chat_stream("deepseek-v4.1-flash", [{"role": "user", "content": "Write a poem"}]):
        print(chunk, end="", flush=True)

    for d in llm.stream("glm-5.3", [{"role": "user", "content": "2+2?"}]):
        ...  # d.content, d.reasoning, d.tool_calls, d.finish_reason, d.usage

    vectors = llm.embed("qwen3-embedding-8b", ["hello", "world"])
    ranked = llm.rerank("qwen3-reranker-8b", "capital of Türkiye",
                        ["Paris is in France", "Ankara is the capital"], top_n=1)
Tool calls use the OpenAI format and are returned in r.tool_calls.
Reliability. On 429, 502, 503, 504 and connection errors the client retries
automatically (max_retries=2), honouring Retry-After. Every non-streaming call
carries an Idempotency-Key, so a retried request is de-duplicated by the gateway
and never executed or billed twice. Streams are retried only when the gateway
rejected them before reaching the model (429/503). An interrupted stream raises
LLMServiceError (code="stream_interrupted") instead of silently returning a
truncated answer. Errors expose status_code, code, param, request_id,
retry_after and the EVREN-specific evren payload (resets_at, suggested_models, …).
When the daily quota is exhausted the gateway sets Retry-After to the end of the
day; such responses (wait longer than 30 s) are not retried and
LLMRateLimitError is raised immediately.
AsyncEvrenLLMClient offers the same API with await / async for.
Typed Decisions, OCR, Speech-to-Text and Quota
Decision models (laya, clef) do not generate text: they answer typed
choice, score and noul (yes/no) questions about a text (and, with clef,
images) in a single pass, with probabilities. llm.models() reports each model's
task (decision, ocr, audio_transcription, …). Laya requires instructions
on every question; include it so the same questions work on both models.
from evren_sdk import EvrenLLMClient, encode_image

with EvrenLLMClient() as llm:
    r = llm.decide("clef", "I was charged twice; refund it or I will cancel.", {
        "team": {"type": "choice", "instructions": "Which team?",
                 "criteria": {"billing": "payments, refunds", "tech": "bugs, outages"}},
        "urgency": {"type": "score", "instructions": "How urgent?", "criteria": ["can wait", "soon", "critical"]},
        "churn": {"type": "noul", "instructions": "Does the customer threaten to cancel?"},
    })
    print(r.choice("team"), r.score("urgency"), r.noul("churn"))

    # clef reads up to 4 images, without downscaling: every 32×32 px tile is one
    # token (1024 px ≈ 1,000, 4000 px ≈ 15,600) — shrink large photos first:
    doc = encode_image("invoice.jpg", max_side=1024)    # pip install evren-sdk[images]
    r = llm.decide("clef", "Inspect the attached document.", {
        "legible": {"type": "noul", "instructions": "Is the total legible?"},
    }, images=[doc])

    batch = llm.decide_batch("laya", ["I forgot my password", "Send me a quote"], {
        "team": {"type": "choice", "instructions": "Which team?", "criteria": {"tech": "login", "sales": "pricing"}},
    })                                                  # laya only; clef has no batch endpoint

    print(llm.ocr("dots-ocr", "receipt.png").text)
    print(llm.transcribe("qwen3-asr-1.7b", "meeting.wav", language="tr").text)
    llm.speak("voxcpm2", "Your report is ready.", voice="kaan", response_format="wav").save("report.wav")  # text-to-speech
    print(llm.quota().daily_remaining_tokens)
    first = llm.respond("glm-5.3", "Capital of Türkiye?")             # Responses API
    print(llm.respond("glm-5.3", "Population?", previous_response_id=first.id).output_text)
The gateway does not accept Idempotency-Key on the audio endpoints, so
transcribe() and speak() are retried only when the connection could not be
established. speak() accepts up to 4,096 characters; the gateway splits long
text at sentence boundaries and returns a single file. voice picks one of four
preset voices (deniz, ece, emre, kaan; default = deniz), and separate
calls with the same voice keep the same speaker. With instructions (an English
voice description) the voice follows the description and is not guaranteed to be
identical across calls.
Edge Mode (GPU-free Devices)
Real-time inference on devices without a GPU (Raspberry Pi, laptops, industrial PCs). Inference runs on EVREN cloud GPUs — the UX feels local.
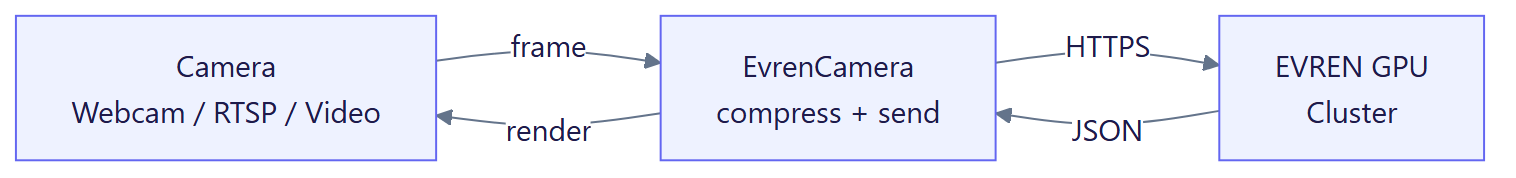
pip install evren-sdk[edge]
from evren_sdk import EvrenCamera

cam = EvrenCamera("evren_...", "owner/model", confidence=0.3)

cam.run(0)                                      # webcam, ESC to quit
cam.record("input.mp4", "output.mp4")           # process + save
for frame, result in cam.stream(0):             # custom loop
    print(f"{result.count} detections")
for path, result in cam.scan("images/"):        # folder scan
    print(f"{path.name}: {result.count} objects")
| Parameter | Default | Description |
|---|---|---|
max_fps |
15.0 |
FPS cap to conserve bandwidth |
jpeg_quality |
70 |
JPEG compression quality (20-95) |
draw |
True |
Render predictions on frame |
confidence |
0.25 |
Minimum confidence threshold |
Error Handling
from evren_sdk import (
    EvrenClient, InsufficientCreditsError,
    NotFoundError, RateLimitError, InferenceError,
)

try:
    result = client.predict("owner/model", "test.jpg")
except InsufficientCreditsError as e:
    print(f"Not enough credits — need: {e.required}, have: {e.available}")
except NotFoundError:
    print("Model not found")
except RateLimitError as e:
    time.sleep(e.retry_after)
except InferenceError:
    print("GPU server temporarily unavailable")
| Exception | HTTP | Description |
|---|---|---|
AuthenticationError |
401, 403 | Invalid or expired key |
InsufficientCreditsError |
402 | Insufficient credits |
NotFoundError |
404 | Model or version not found |
ValidationError |
422 | Invalid parameter |
RateLimitError |
429 | Rate limit exceeded |
InferenceError |
502, 503 | GPU server error |
Every inference call consumes credits. When balance is too low, the SDK raises
InsufficientCreditsErrorwithe.requiredande.availablefields.
API Reference
Data Models
| Class | Fields / Methods |
|---|---|
PredictResult |
predictions, inference_ms, count, image_width, image_height |
| ↳ methods | filter(), to_yolo(), to_coco(), to_csv(), save() |
Prediction |
class_name, confidence, bbox, color, mask, keypoints, obb |
| ↳ methods | to_dict() |
BatchResult |
results, total_ms, count — iterable, supports len() |
BenchmarkResult |
model, rounds, avg_ms, min_ms, max_ms, p95_ms, throughput_fps |
ModelClasses |
classes, architecture, model_name, total, imgsz — supports in |
| ↳ methods | names() |
ModelInfo |
id, name, slug, architecture, owner_username, full_slug |
ModelVersion |
id, version_tag, framework, metrics, weights_url |
ClassInfo |
name, color |
EvrenCamera |
stream(), run(), scan(), record(), stats |
Client Methods
| Method | Description |
|---|---|
predict(model, image, **kw) |
Single inference |
predict_batch(model, images, **kw) |
GPU batch inference |
model_classes(model) |
Model classes, architecture, imgsz |
warmup(models) |
GPU pre-load |
list_models(limit) |
List available models |
list_versions(model_id) |
List model versions |
resolve(slug) |
Slug → version UUID |
benchmark(model, image, **kw) |
Performance test |
download_model(model, output, fmt) |
Download weights |
upload_to_dataset(dataset_id, image) |
Upload image to dataset |
AsyncEvrenClient provides the same API with async/await.
LLM Client Methods
| Method | Endpoint | Returns |
|---|---|---|
chat(model, messages, **kw) |
/v1/chat/completions |
ChatCompletionResult |
stream() / chat_stream() |
/v1/chat/completions (SSE) |
ChatDelta / str |
embed(model, texts) |
/v1/embeddings |
list[list[float]] |
rerank(model, query, documents, top_n) |
/v1/rerank |
list[RerankResult] |
decide(model, state, questions, images=) |
/v1/systemone |
DecisionResult |
decide_batch(model, states, questions) |
/v1/systemone/batch |
DecisionBatchResult |
ocr(model, image) |
/v1/ocr |
OcrResult |
transcribe(model, audio, response_format=) |
/v1/audio/transcriptions |
Transcription |
speak(model, text, voice=, response_format=, instructions=) |
/v1/audio/speech |
SpeechResult |
respond(model, input, **kw) / get_response(id) |
/v1/responses |
ResponseResult |
models() / list_models() |
/v1/models |
list[LLMModel] / list[str] |
quota() |
/v1/quota |
QuotaStatus |
request_status(request_id) |
/v1/requests/{id} |
RequestStatus |
encode_image(source, max_side=None) turns a path, bytes or data: URL into the
embedded form the gateway accepts.
Examples
| # | File | Description |
|---|---|---|
| 1 | 01_quickstart.py |
Temel tekil çıkarım / Basic single prediction |
| 2 | 02_batch_inference.py |
Toplu GPU çıkarım / Batch GPU inference |
| 3 | 03_result_export.py |
Filtreleme & export (YOLO, COCO, CSV, JSON) |
| 4 | 04_benchmark.py |
Performans testi / Latency & throughput |
| 5 | 05_edge_camera.py |
Edge cihaz kamera / GPU-free real-time |
| 6 | 06_upload_to_dataset.py |
Veri setine görsel yükleme / Upload images to dataset |
| 7 | 07_async_pipeline.py |
Asenkron paralel çıkarım / Async pipeline |
Requirements
- Python >= 3.10
- httpx >= 0.27
- opencv-python >= 4.8 (only for
evren-sdk[edge]) - Pillow >= 10 (only for
encode_image(max_side=...),evren-sdk[images])